
Python Check If Value Is NaN: A Complete Overview
Introduction
When working with numeric data in Python, sooner or later you will encounter NaN, short for “Not a Number.” NaN values are common in data analysis, machine learning, financial calculations, imported datasets, and applications that process incomplete information.
The challenge is that NaN behaves differently from ordinary numbers. A missing or undefined value that goes unnoticed can affect calculations, statistics, model inputs, reports, and business decisions without necessarily causing an obvious application error.
This guide explains how to check if a value is NaN in Python, where NaN values come from, and how to work with them using the standard library, NumPy, and pandas. It also covers an equally important question: what should you actually do after finding missing values?
What Is NaN in Python?
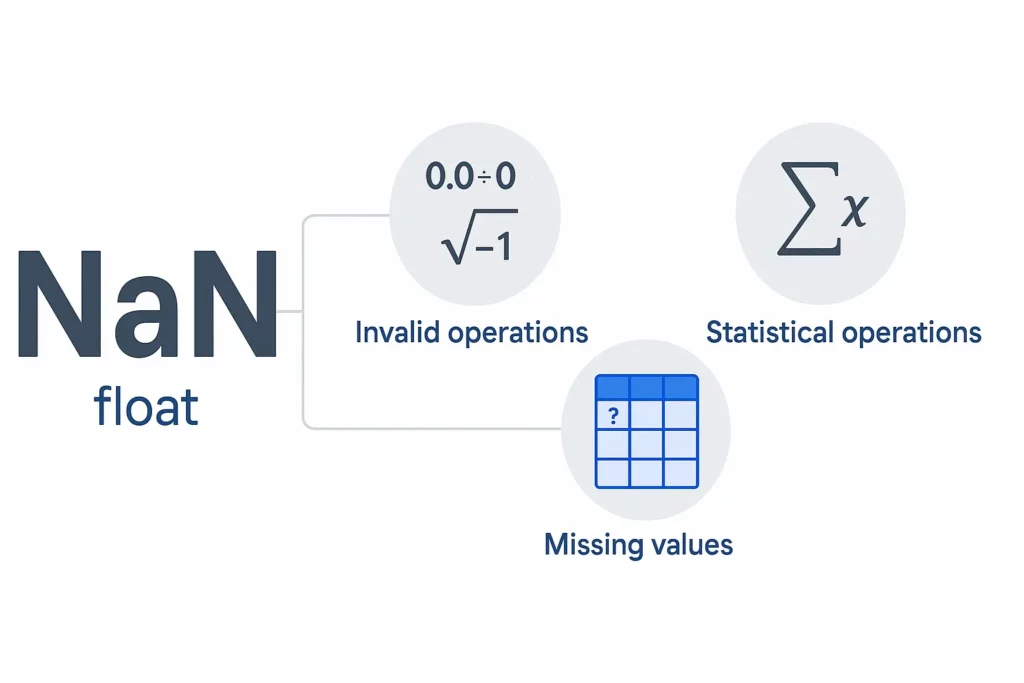
NaN means Not a Number. It is a special floating-point value based on the IEEE 754 floating-point standard and is used to represent numerical results that are undefined or unavailable.
Despite its name, NaN is still represented as a floating-point value in Python rather than as a separate “missing data” type.
NaN can appear for several reasons:
- a numerical operation produces an undefined result;
- information is missing from an imported dataset;
- a measurement was not recorded;
- an external system did not provide a value;
- data could not be converted into a meaningful numeric result;
- an analytical operation encounters incomplete observations.
One unusual characteristic makes NaN particularly important to understand: NaN does not compare as equal to itself.
A very small example demonstrates the behavior:
import math

value = float("nan")

print(value == value)       # False
print(math.isnan(value))    # True
This is why checking value == NaN is not a reliable way to identify NaN values. Python applications should instead use a function designed for the type of data being processed.
Where Does NaN Appear in Python?
NaN is often associated with data science, but it can appear in many kinds of Python applications.
Numerical Computations
Some numerical libraries can produce NaN when a calculation has no meaningful result in the relevant numerical domain. This is particularly common in scientific and statistical workloads involving floating-point data.
The important point is that a NaN value may continue through subsequent calculations. If it is not detected, it can eventually affect aggregations, reports, or other outputs far removed from the original operation.
Imported and Incomplete Data
Real-world datasets are rarely perfect. A CSV may contain an empty field, a spreadsheet may have an unanswered cell, or a database record may lack a value.
Data-processing libraries such as pandas provide missing-value representations and APIs for detecting them. This is one reason NaN checks are such a routine part of data cleaning.
Machine Learning and Analytics
Machine learning datasets frequently contain incomplete observations. A customer may skip a survey question, a sensor may temporarily stop transmitting, or a historical record may be missing one feature.
Whether those missing values should be removed, replaced, preserved, or modeled separately depends on what the data represents.
APIs and External Systems
Applications increasingly combine information from multiple services. An API response may omit a metric, an integration may fail to supply a field, or data from different systems may use different conventions for representing missing information.
For this reason, missing-value validation is useful not only in notebooks and analytical scripts but also at application and integration boundaries.
How to Check If a Value Is NaN in Python

There is no single NaN-checking method that is ideal for every Python workload. The appropriate approach depends mainly on whether you are working with an individual numeric value, a NumPy array, or pandas data.
Using math.isnan()
For an individual numeric value in standard Python code, math.isnan() is usually the clearest option.
It communicates exactly what the program is testing and does not require an external data-processing library.
However, it is not designed as a universal missing-value detector. Applications receiving mixed input such as strings, None, and numbers should validate the type and meaning of that input rather than assuming every value can be passed directly to a numerical function.
Using numpy.isnan()
For NumPy arrays and numerical workloads, numpy.isnan() is generally more appropriate. It can perform element-wise checks across numerical arrays instead of requiring developers to examine each element with a Python loop.
That distinction matters when working with scientific computing, simulations, numerical transformations, or large arrays where vectorized operations are central to the workflow.
Using pandas.isna()
For pandas Series and DataFrames, pandas.isna() provides a higher-level missing-data check. It is designed for pandas data structures and can account for several forms of missing information used within the pandas ecosystem.
This makes it a practical choice for imported datasets, reporting pipelines, analytics, and other tabular-data workloads.
Which NaN Check Should You Use?
The simplest rule is to select the method that matches the data structure already used by your application.
| Method | Best Used For | Main Advantage | Consideration |
|---|---|---|---|
math.isnan() |
Individual numerical values | Simple and available in Python’s standard library | Not a general-purpose missing-data API for arbitrary input |
numpy.isnan() |
Numerical arrays and scientific computing | Efficient element-wise checking | Input type and array dtype still matter |
pandas.isna() |
Series, DataFrames, and tabular data | Works with pandas missing-value conventions | Requires pandas and should be understood in the context of column dtypes |
For a single calculation, bringing pandas into a project only to check one float would add unnecessary complexity. Conversely, manually looping through a large DataFrame with math.isnan() would ignore the tools pandas already provides.
NaN vs None: What Is the Difference?
One common source of confusion is treating NaN and None as interchangeable.
None is Python’s built-in singleton used to represent the absence of a value or object. NaN, by contrast, originates from floating-point numerical semantics. They can therefore mean similar things at the business level—“we don’t have a usable value”—while remaining technically different.
The distinction becomes especially important when data moves between Python, pandas, NumPy, databases, JSON APIs, and external systems. Different layers may represent missing information differently.
Modern pandas also has additional missing-value concepts depending on the data type. That means production code should avoid assuming that every missing field will literally contain float(“nan”).
A better strategy is to decide what “missing” means for the application and then use the missing-data API appropriate for the data structure. In pandas workflows, for example, isna() and notna() are usually more robust than checking for one specific sentinel value.
This distinction also has business implications. A missing value is not necessarily the same as zero, an empty string, “unknown,” or “not applicable.” Converting all of these states into one representation can destroy information that may matter later.
Why NaN == NaN Returns False

The fact that NaN does not equal itself often surprises developers seeing it for the first time. However, this behavior is intentional and follows floating-point semantics rather than being a Python bug.
Conceptually, NaN represents a result that cannot be treated as an ordinary numeric value. Comparing two such results does not establish that they represent the same number.
This is why code based on direct equality can produce unexpected results. It can affect filtering, conditional logic, deduplication, and validation if developers assume NaN behaves like an ordinary number.
The practical rule is straightforward: do not use ordinary equality as your primary NaN test. Use math.isnan(), numpy.isnan(), or the appropriate pandas missing-data function depending on the context.
This also highlights a broader engineering principle: missing data should be handled explicitly. Relying on incidental equality behavior makes code harder to understand and easier to break when the underlying data representation changes.
Common NaN Mistakes to Avoid
Detecting NaN correctly is only part of the problem. Several mistakes can create subtle issues in real applications.
Treating NaN as zero. A missing sales amount does not necessarily mean that no sales occurred. Replacing missing information with zero can change totals, averages, forecasts, and business conclusions.
Assuming every missing value is NaN. Depending on the library and data type, missing information may also appear as None, pandas-specific missing values, or other representations.
Confusing infinity with NaN. Positive and negative infinity are special floating-point values, but they are not NaN. Applications that need to validate all non-finite numbers should account for this distinction.
Ignoring data types. Missing-value behavior can differ between floating-point, integer, string, object, datetime, and nullable columns.
Cleaning data without understanding why it is missing. Automatically dropping or replacing every NaN can remove useful information. Sometimes the fact that a value is missing is itself analytically meaningful.
The safest approach is therefore not simply “find NaN and remove it.” Detection should be followed by a decision based on data meaning and application requirements.
How Should You Handle NaN After Detecting It?
Once a missing value has been identified, there are several possible strategies. The right one depends on why the value is missing and how the data will be used.
Remove Missing Records
Removing rows or columns can be reasonable when missing data represents a very small part of the dataset and losing those observations will not materially affect the analysis.
The risk is that missingness may not be random. If a particular customer group, device type, region, or time period is more likely to have missing data, dropping those records can introduce bias.
Replace NaN with a Default Value
Replacing NaN with zero, “Unknown,” or another default can simplify downstream processing, but only when that replacement has a defensible meaning.
A zero revenue value, for example, makes a very different statement from an unknown revenue value.
Use Statistical Imputation
For analytical and machine learning workloads, missing numerical values may sometimes be replaced using a mean, median, mode, or another statistical method.
This can preserve dataset size, but imputation changes the data. The method should therefore reflect the distribution, analytical objective, and assumptions behind the model rather than being applied mechanically.
Use Domain-Specific Rules
In production systems, business knowledge often provides a better answer than a generic statistical technique.
An e-commerce application might recover missing product information from a catalog system. A financial platform may require a transaction to be rejected rather than estimated. An IoT application may use a previous sensor measurement only when the gap falls within an acceptable time window.
Keep NaN Intentionally
Sometimes missingness itself is useful information. A missing sensor measurement may indicate hardware failure, while an unanswered form field may reveal a behavioral pattern.
Preserving the missing value—or creating a separate missingness indicator—can therefore be more informative than replacing it.
Why Missing-Value Strategy Matters in Real Applications
NaN handling is often presented as a small data-cleaning task, but in production systems it can affect much more than whether a calculation succeeds.
Consider a reporting platform. If missing revenue values are automatically converted to zero, management dashboards may underestimate revenue. If those rows are simply removed, averages and customer counts may change instead. Neither decision is neutral.
The same problem appears in machine learning. Missing values can affect feature distributions and model behavior, while an inappropriate imputation strategy can introduce patterns that did not exist in the original data.
In operational software, missing values can also signal upstream failures. A field that is suddenly absent from thousands of API responses may indicate an integration change rather than poor-quality data.
For this reason, robust custom software development should treat missing-data handling as part of data validation and application design. Teams need to define which fields are optional, how missing states are represented, where validation occurs, and what should happen when required information is unavailable.
A good NaN strategy is therefore not just a Python implementation detail. It is part of maintaining trustworthy data throughout the system.
Handling NaN in Data Pipelines
Missing values become more difficult to manage when data moves through multiple stages rather than being processed in a single script.
A typical pipeline might receive information from an API, store it in a database, transform it with Python, aggregate it for analytics, and finally expose it in a dashboard. At every stage, the representation or meaning of missing information can change.
Teams should therefore define a consistent policy for missing data. Useful questions include:
- Which fields are allowed to be missing?
- Does missing mean unknown, unavailable, not applicable, or invalid?
- Should a missing required value reject a record?
- Where should imputation occur?
- Should original missingness be preserved for auditing?
- How should missing values appear in reports and APIs?
- What happens if the percentage of missing records suddenly increases?
These decisions are particularly important for systems that combine multiple data sources. Consistent rules make pipelines easier to debug and reduce the risk that one component silently interprets missing data differently from another.
Monitoring can also help. A sudden increase in missing values can indicate an upstream schema change, broken integration, sensor problem, or data-quality incident before users notice incorrect results.
Performance Considerations When Checking NaN
Performance usually does not matter when checking one or two values, but the implementation approach becomes more important as datasets grow.
For numerical arrays, NumPy’s vectorized operations are generally more appropriate than manually iterating over every element in Python. Likewise, pandas provides operations designed to work across entire Series and DataFrames.
The broader principle is to work at the abstraction level of the library you are already using. If your application processes a pandas DataFrame, use pandas operations for missing-data detection and transformation. If it performs numerical computing with NumPy arrays, use NumPy’s array-oriented tools.
Developers should also be careful about creating unnecessary copies of large datasets or repeatedly transforming the same columns. Memory usage can become as important as raw execution time.
For datasets that exceed available memory, the solution may involve processing data in chunks or redesigning the pipeline rather than merely optimizing an individual NaN check.
Most applications should prioritize correctness and clarity first. Performance optimization becomes valuable after profiling identifies missing-data operations as a meaningful bottleneck.
Choosing the Right NaN Strategy
There is no universal “best” method for detecting and handling NaN. A useful decision framework is to consider both the technical data type and the business meaning of the missing value.
| Situation | Typical Approach | Key Question |
|---|---|---|
| Single numeric value | Use a standard numerical NaN check | Is the input guaranteed to be numeric? |
| NumPy numerical data | Use vectorized NumPy checks | Do you need to detect NaN only or all non-finite values? |
| pandas dataset | Use pandas missing-data APIs | Which missing representations and dtypes are present? |
| Analytics or ML dataset | Detect first, then choose removal or imputation deliberately | Could the chosen treatment bias the results? |
| Production data pipeline | Define validation and missing-data rules across the system | What does a missing value mean to the business? |
The most important distinction is between detecting a missing value and deciding what to do with it. Python libraries can solve the first problem. The second usually requires knowledge of the application, dataset, and business rules.
Checking whether a value is NaN in Python is straightforward once you choose the method that matches your data. math.isnan() is useful for individual numerical values, NumPy provides efficient checks for numerical arrays, and pandas offers missing-data APIs designed for Series and DataFrames.
The more important challenge begins after detection. A NaN value can represent missing information, an undefined calculation, an upstream data problem, or a meaningful signal. Automatically replacing or removing it without understanding that context can produce technically valid but misleading results.
Reliable applications therefore treat missing-data handling as part of a broader data-quality strategy. Teams should understand where missing values originate, decide how different missing states should be represented, validate important fields, and monitor unexpected changes in data quality.
With that approach, NaN handling becomes more than a defensive programming technique. It helps keep analytics, machine learning pipelines, integrations, and business applications accurate and predictable.
Handling NaN correctly is one small part of building reliable data-intensive software. Production Python applications also require thoughtful data validation, architecture, integrations, testing, performance optimization, and maintainable development practices.
Digis provides Python development services for companies building backend platforms, data-driven applications, automation systems, and custom software.
Need experienced Python engineers for your project? Contact Digis to discuss your requirements and find the right development approach.
FAQ
What Is the Difference Between NaN and None in Python?
NaN and None can both represent missing information, but they are technically different. NaN is associated with floating-point numerical semantics, while None is Python’s built-in object representing the absence of a value.
Libraries such as pandas provide missing-data functions that can recognize multiple missing representations, which is generally safer than assuming every missing value will have the same underlying type.
Why Is NaN Not Equal to Itself?
NaN follows floating-point rules in which it represents an unordered or undefined numerical result. As a consequence, an equality comparison involving NaN does not behave like equality between ordinary numbers.
This is why direct equality should not be used to determine whether a value is NaN. Use the appropriate missing-value or NaN-checking function instead.
What Is the Best Way to Check for NaN in Python?
It depends on the data. For an individual numeric value, math.isnan() is usually sufficient. For NumPy arrays, numpy.isnan() is designed for element-wise numerical checks. For pandas Series and DataFrames, pandas.isna() is generally the most appropriate option.
Choosing the method that matches your existing data structure usually produces clearer and more maintainable code.
Are NaN and Infinity the Same Thing?
No. NaN represents an undefined or unordered numerical value, while positive and negative infinity represent values beyond the finite floating-point range or results with infinite magnitude.
If an application needs to validate numerical data comprehensively, it may need to distinguish between NaN, positive infinity, negative infinity, and valid finite numbers.
Should I Replace Every NaN with Zero?
Usually not. Zero is a real numerical value, while NaN often means that a value is unknown or unavailable. Replacing every NaN with zero can therefore change the meaning of the dataset and distort calculations.
Use zero only when it is a valid representation of the missing information according to the business or analytical context.
Should I Drop Rows That Contain NaN?
Only when losing those rows is acceptable. Dropping missing observations can be appropriate when they are rare and their absence will not bias the analysis.
Before removing them, investigate how much data is missing and whether particular groups or situations are disproportionately affected.
Can pandas Handle Missing Values in Integer Columns?
Yes. pandas supports nullable data types that allow missing values in data that conceptually represents integers and other types.
This is useful because converting integer data to floating point solely to accommodate NaN may not always be desirable. The appropriate dtype depends on how the dataset will be processed.
Can NaN Affect Machine Learning Models?
Yes. Missing values can affect training, preprocessing, feature distributions, evaluation, and predictions. Some modeling approaches can handle missing values directly, while others require preprocessing.
The treatment should be part of the machine learning pipeline rather than an arbitrary cleaning step performed without considering the model and dataset.
Is It Better to Remove or Impute Missing Values?
Neither option is universally better. Removal can reduce dataset size or introduce bias, while imputation introduces estimated values that were not originally observed.
The correct choice depends on why data is missing, how much is missing, the analytical objective, and the consequences of changing or removing observations.
 +44 204 577 2743
 +1 929 342 4696